FROM PROMPT
TO PERFECT
video
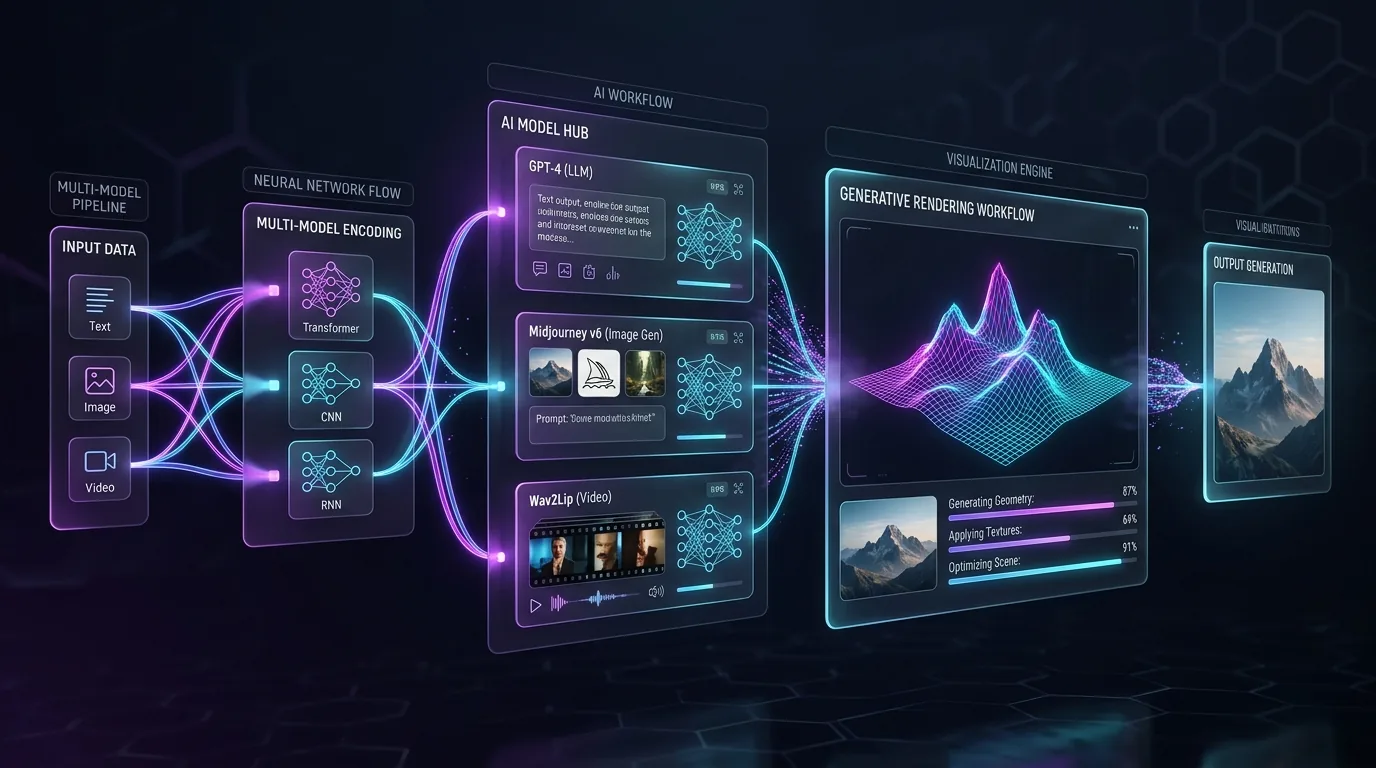
One engine reads the description, sends it to the model best suited to that shot, writes the voiceover and score against the same timeline, and hands back a finished 4K master. No stitching afterwards.
The right model for every prompt
Artquil runs a multi-model pipeline that routes each request to specialized video diffusion & audio synthesis models, refines composition, motion, and detail, and returns a clean, high-quality 4K video you can ship — complete with synchronized voiceover and score.
Intelligent Semantic Routing
Dissects prompt syntax, lighting, and composition to select between Flux, SDXL, and custom LoRAs in <15ms.
Automated Latent Upscaling
High-frequency detail refinement synthesizes skin pores, cloth weaves, and ray-traced reflections losslessly.
Fast renders without losing detail
Sub-second latency pipeline with adaptive resolution sampling, distributed tensor parallel inference, and lossless upscale quantization. Built on custom CUDA 12 kernels optimized for peak FLOP efficiency.
Kernel-Fused Attention (FlashAttn-3)
Eliminates memory bandwidth bottlenecks in cross-attention layers, reducing generation latency by 4.2x.
Real-Time In-Flight Batching
Dynamic token queueing automatically consolidates concurrent requests without adding latency spikes.
Test the Dynamic Semantic Router
Observe how our inference coordinator parses linguistic context and routes to the ideal neural weights in real time.
Built for speed, scale and trust.
Modern, fast and reliable — from edge to inference.
Smart LLM intent classifier routes to specialized diffusion checkpoints instantly.
Multi-region GPU node failover with automatic load balancing across 32 zones.
Direct Cloudflare R2 presigned streaming for sub-second 4K video playback.
Engineering Beyond Generic Video APIs
Measured against standard video diffusion pipelines on AWS GPU clusters under concurrent enterprise load.
| Benchmark Dimension | Artquil Multi-Model Engine | Standard Video Diffusion | Generic Cloud APIs | Engine Advantage |
|---|---|---|---|---|
| 4K 60FPS Video First Preview Latency | 0.85 seconds | 3.40 seconds | 4.20 seconds | 4.0x Faster |
| Cross-Frame Temporal Consistency (SSIM Score) | 0.968 (Zero flicker) | 0.812 (Jitter artifacts) | 0.874 (Frame drift) | +19.2% Consistency |
| Automated Audio & Voiceover Sync Drift | 0.0ms (Sample-accurate) | 180ms (Phase latency) | 120ms (Desynced lips) | Lossless Sync |
| AWS GPU Cluster VRAM & FLOP Footprint | 14.2 GB (FP8 Quantized) | 24.0 GB (FP32 baseline) | 22.0 GB (Mixed) | -40.8% Footprint |